---
title: AI Changelog
image: https://developers.cloudflare.com/og-changelog.png
---
[Skip to content](#main-content)
All products
Product groups
AI
Analytics
Application performance
Application security
Cloudflare One
Consumer services
Core platform
Developer platform
Docs collections
Media
Network security
Privacy
Storage
Products
1.1.1.1 (DNS Resolver)
Access
Agent Lee
Agents
AI Crawl Control
AI Gateway
AI Search
Analytics
API Shield
Artifacts
Audit Logs
Automatic Platform Optimization
Basin
Basin Catalog
Basin Pipelines
Basin SQL
Billing
Bots
Browser Isolation
Browser Run
BYOIP
Cache / CDN
CASB
Challenges
China Network
Cloud Workload Security
Cloudflare CLI
Cloudflare for SaaS
Cloudflare Fundamentals
Cloudflare Images
Cloudflare Mesh
Cloudflare Network Firewall
Cloudflare One
Cloudflare One Appliance
Cloudflare One Client
Cloudflare Tunnel
Cloudflare Tunnel for SASE
Cloudflare WAN
Cloudflare Web Analytics
Containers
D1
Data Localization Suite
Data Loss Prevention
Digital Experience Monitoring
DNS
Durable Objects
Email security
Email Service
Flagship
Gateway
Go SDK
Hyperdrive
KV
Load Balancing
Log Explorer
Logpush
Logpush Connectors
Logs
Magic Transit
Monetization Gateway
Multi-Cloud Networking
Network Flow
Network Interconnect
Notifications
Organizations
Pages
Privacy Proxy
Queues
R2
Radar
Realtime
Registrar
Resource Tagging
Risk Score
Rules
Sandboxes
SDK
Secrets Store
Security Center
Security Overview
Speed
SSL/TLS
Stream
Support
Terraform
Turnstile
Vectorize
WAF
Web Search API
Workers
Workers AI
Workers Analytics Engine
Workers for Platforms
Workers VPC
Workflows
Zaraz
No products found.
[View RSS feeds](https://developers.cloudflare.com/fundamentals/new-features/available-rss-feeds/) [ Subscribe to RSS](https://developers.cloudflare.com/changelog/rss/index.xml)
Oct 31, 2025
[Workers WebSocket message size limit increased from 1 MiB to 32 MiB
](https://developers.cloudflare.com/changelog/post/2025-10-31-increased-websocket-message-size-limit/)
[Workers](https://developers.cloudflare.com/workers/) [Durable Objects](https://developers.cloudflare.com/durable-objects/) [Browser Run](https://developers.cloudflare.com/browser-run/)
Workers, including those using [Durable Objects](https://developers.cloudflare.com/durable-objects/) and [Browser Rendering](https://developers.cloudflare.com/browser-run/), may now process WebSocket messages up to 32 MiB in size. Previously, this limit was 1 MiB.
This change allows Workers to handle use cases requiring large message sizes, such as processing Chrome Devtools Protocol messages.
For more information, please see the [Durable Objects startup limits](https://developers.cloudflare.com/durable-objects/platform/limits/#sqlite-backed-durable-objects-general-limits).
Oct 28, 2025
[Reranking and API-based system prompt configuration in AI Search
](https://developers.cloudflare.com/changelog/post/2025-10-27-ai-search-reranking-system-prompt/)
[AI Search](https://developers.cloudflare.com/ai-search/)
[AI Search](https://developers.cloudflare.com/ai-search/) now supports reranking for improved retrieval quality and allows you to set the system prompt directly in your API requests.
#### Rerank for more relevant results
You can now enable [reranking](https://developers.cloudflare.com/ai-search/configuration/retrieval/reranking/) to reorder retrieved documents based on their semantic relevance to the user’s query. Reranking helps improve accuracy, especially for large or noisy datasets where vector similarity alone may not produce the optimal ordering.
You can enable and configure reranking in the dashboard or directly in your API requests:
```javascript
const answer = await env.AI.autorag("my-autorag").aiSearch({
query: "How do I train a llama to deliver coffee?",
model: "@cf/meta/llama-3.3-70b-instruct-fp8-fast",
reranking: {
enabled: true,
model: "@cf/baai/bge-reranker-base",
},
});
```
#### Set system prompts in API
Previously, [system prompts](https://developers.cloudflare.com/ai-search/configuration/retrieval/system-prompt/) could only be configured in the dashboard. You can now define them directly in your API requests, giving you per-query control over behavior. For example:
```javascript
// Dynamically set query and system prompt in AI Search
async function getAnswer(query, tone) {
const systemPrompt = `You are a ${tone} assistant.`;
const response = await env.AI.autorag("my-autorag").aiSearch({
query: query,
system_prompt: systemPrompt,
});
return response;
}
// Example usage
const query = "What is Cloudflare?";
const tone = "friendly";
const answer = await getAnswer(query, tone);
console.log(answer);
```
Learn more about [Reranking](https://developers.cloudflare.com/ai-search/configuration/retrieval/reranking/) and [System Prompt](https://developers.cloudflare.com/ai-search/configuration/retrieval/system-prompt/) in AI Search.
Oct 23, 2025
[Workers AI Markdown Conversion: New endpoint to list supported formats
](https://developers.cloudflare.com/changelog/post/2025-10-23-new-markdown-conversion-endpoint/)
[Workers AI](https://developers.cloudflare.com/workers-ai/)
Developers can now programmatically retrieve a list of all file formats supported by the [Markdown Conversion utility](https://developers.cloudflare.com/workers-ai/features/markdown-conversion/) in Workers AI.
You can use the [`env.AI`](https://developers.cloudflare.com/workers-ai/configuration/bindings/) binding:
```typescript
await env.AI.toMarkdown().supported()
```
Or call the REST API:
```bash
curl https://api.cloudflare.com/client/v4/accounts/{ACCOUNT_ID}/ai/tomarkdown/supported \
-H 'Authorization: Bearer {API_TOKEN}'
```
Both return a list of file formats that users can convert into Markdown:
```json
[
{
"extension": ".pdf",
"mimeType": "application/pdf",
},
{
"extension": ".jpeg",
"mimeType": "image/jpeg",
},
...
]
```
Learn more about our [Markdown Conversion utility](https://developers.cloudflare.com/workers-ai/features/markdown-conversion/).
Oct 21, 2025
[New Robots.txt tab for tracking crawler compliance
](https://developers.cloudflare.com/changelog/post/2025-10-21-track-robots-txt/)
[AI Crawl Control](https://developers.cloudflare.com/ai-crawl-control/)
AI Crawl Control now includes a **Robots.txt** tab that provides insights into how AI crawlers interact with your `robots.txt` files.
#### What's new
The Robots.txt tab allows you to:
- Monitor the health status of `robots.txt` files across all your hostnames, including HTTP status codes, and identify hostnames that need a `robots.txt` file.
- Track the total number of requests to each `robots.txt` file, with breakdowns of successful versus unsuccessful requests.
- Check whether your `robots.txt` files contain [Content Signals ↗︎](https://contentsignals.org/) directives for AI training, search, and AI input.
- Identify crawlers that request paths explicitly disallowed by your `robots.txt` directives, including the crawler name, operator, violated path, specific directive, and violation count.
- Filter `robots.txt` request data by crawler, operator, category, and custom time ranges.
#### Take action
When you identify non-compliant crawlers, you can:
- Block the crawler in the [Crawlers tab](https://developers.cloudflare.com/ai-crawl-control/features/manage-ai-crawlers/)
- Create custom [WAF rules](https://developers.cloudflare.com/waf/) for path-specific security
- Use [Redirect Rules](https://developers.cloudflare.com/rules/url-forwarding/) to guide crawlers to appropriate areas of your site
To get started, go to **AI Crawl Control** > **Robots.txt** in the Cloudflare dashboard. Learn more in the [Track robots.txt documentation](https://developers.cloudflare.com/ai-crawl-control/features/track-robots-txt/).
Oct 14, 2025
[Enhanced AI Crawl Control metrics with new drilldowns and filters
](https://developers.cloudflare.com/changelog/post/2025-10-14-enhanced-metrics-drilldowns/)
[AI Crawl Control](https://developers.cloudflare.com/ai-crawl-control/)
AI Crawl Control now provides enhanced metrics and CSV data exports to help you better understand AI crawler activity across your sites.
#### What's new
#### Track crawler requests over time
Visualize crawler activity patterns over time, and group data by different dimensions:
- **By Crawler** — Track activity from individual AI crawlers (GPTBot, ClaudeBot, Bytespider)
- **By Category** — Analyze crawler purpose or type
- **By Operator** — Discover which companies (OpenAI, Anthropic, ByteDance) are crawling your site
- **By Host** — Break down activity across multiple subdomains
- **By Status Code** — Monitor HTTP response codes to crawlers (200s, 300s, 400s, 500s)

*Interactive chart showing crawler requests over time with filterable dimensions*
#### Analyze referrer data (Paid plans)
Identify traffic sources with referrer analytics:
- View top referrers driving traffic to your site
- Understand discovery patterns and content popularity from AI operators

*Bar chart showing top referrers and their respective traffic volumes*
#### Export data
Download your filtered view as a CSV:
- Includes all applied filters and groupings
- Useful for custom reporting and deeper analysis
#### Get started
1. Log in to the Cloudflare dashboard, and select your account and domain.
2. Go to **AI Crawl Control** > **Metrics**.
3. Use the grouping tabs to explore different views of your data.
4. Apply filters to focus on specific crawlers, time ranges, or response codes.
5. Select **Download CSV** to export your filtered data for further analysis.
Learn more about [AI Crawl Control](https://developers.cloudflare.com/ai-crawl-control).
Oct 2, 2025
[New Deepgram Flux model available on Workers AI
](https://developers.cloudflare.com/changelog/post/2025-10-02-deepgram-flux/)
[Workers AI](https://developers.cloudflare.com/workers-ai/)
Deepgram's newest Flux model [`@cf/deepgram/flux`](https://developers.cloudflare.com/workers-ai/models/flux/) is now available on Workers AI, hosted directly on Cloudflare's infrastructure. We're excited to be a launch partner with Deepgram and offer their new Speech Recognition model built specifically for enabling voice agents. Check out [Deepgram's blog ↗︎](https://deepgram.com/flux) for more details on the release.
The Flux model can be used in conjunction with Deepgram's speech-to-text model [`@cf/deepgram/nova-3`](https://developers.cloudflare.com/workers-ai/models/nova-3/) and text-to-speech model [`@cf/deepgram/aura-1`](https://developers.cloudflare.com/workers-ai/models/aura-1/) to build end-to-end voice agents. Having Deepgram on Workers AI takes advantage of our edge GPU infrastructure, for ultra low latency voice AI applications.
#### Promotional Pricing
For the month of October 2025, Deepgram's Flux model will be free to use on Workers AI. Official pricing will be announced soon and charged after the promotional pricing period ends on October 31, 2025. Check out the [model page](https://developers.cloudflare.com/workers-ai/models/flux/) for pricing details in the future.
#### Example Usage
The new Flux model is WebSocket only as it requires live bi-directional streaming in order to recognize speech activity.
1. Create a worker that establishes a websocket connection with `@cf/deepgram/flux`
```js
export default {
async fetch(request, env, ctx): Promise {
const resp = await env.AI.run("@cf/deepgram/flux", {
encoding: "linear16",
sample_rate: "16000"
}, {
websocket: true
});
return resp;
},
} satisfies ExportedHandler;
```
2. Deploy your worker
```bash
npx wrangler deploy
```
3. Write a client script to connect to your worker and start sending random audio bytes to it
```js
const ws = new WebSocket('wss://');
ws.onopen = () => {
console.log('Connected to WebSocket');
// Generate and send random audio bytes
// You can replace this part with a function
// that reads from your mic or other audio source
const audioData = generateRandomAudio();
ws.send(audioData);
console.log('Audio data sent');
};
ws.onmessage = (event) => {
// Transcription will be received here
// Add your custom logic to parse the data
console.log('Received:', event.data);
};
ws.onerror = (error) => {
console.error('WebSocket error:', error);
};
ws.onclose = () => {
console.log('WebSocket closed');
};
// Generate random audio data (1 second of noise at 44.1kHz, mono)
function generateRandomAudio() {
const sampleRate = 44100;
const duration = 1;
const numSamples = sampleRate * duration;
const buffer = new ArrayBuffer(numSamples * 2);
const view = new Int16Array(buffer);
for (let i = 0; i < numSamples; i++) {
view[i] = Math.floor(Math.random() * 65536 - 32768);
}
return buffer;
}
```
Sep 25, 2025
[Browser Rendering Playwright GA, Stagehand support (Beta), and higher limits
](https://developers.cloudflare.com/changelog/post/2025-09-25-br-playwright-ga-stagehand-limits/)
[Browser Run](https://developers.cloudflare.com/browser-run/)
We’re shipping three updates to Browser Rendering:
- Playwright support is now Generally Available and synced with [Playwright v1.55 ↗︎](https://playwright.dev/docs/release-notes#version-155), giving you a stable foundation for critical automation and AI-agent workflows.
- We’re also adding [Stagehand support (Beta)](https://developers.cloudflare.com/browser-run/stagehand/) so you can combine code with natural language instructions to build more resilient automations.
- Finally, we’ve tripled [limits](https://developers.cloudflare.com/browser-run/limits/#workers-paid) for paid plans across both the [REST API](https://developers.cloudflare.com/browser-run/quick-actions/) and [Browser Sessions](https://developers.cloudflare.com/browser-run/#integration-methods) to help you scale.
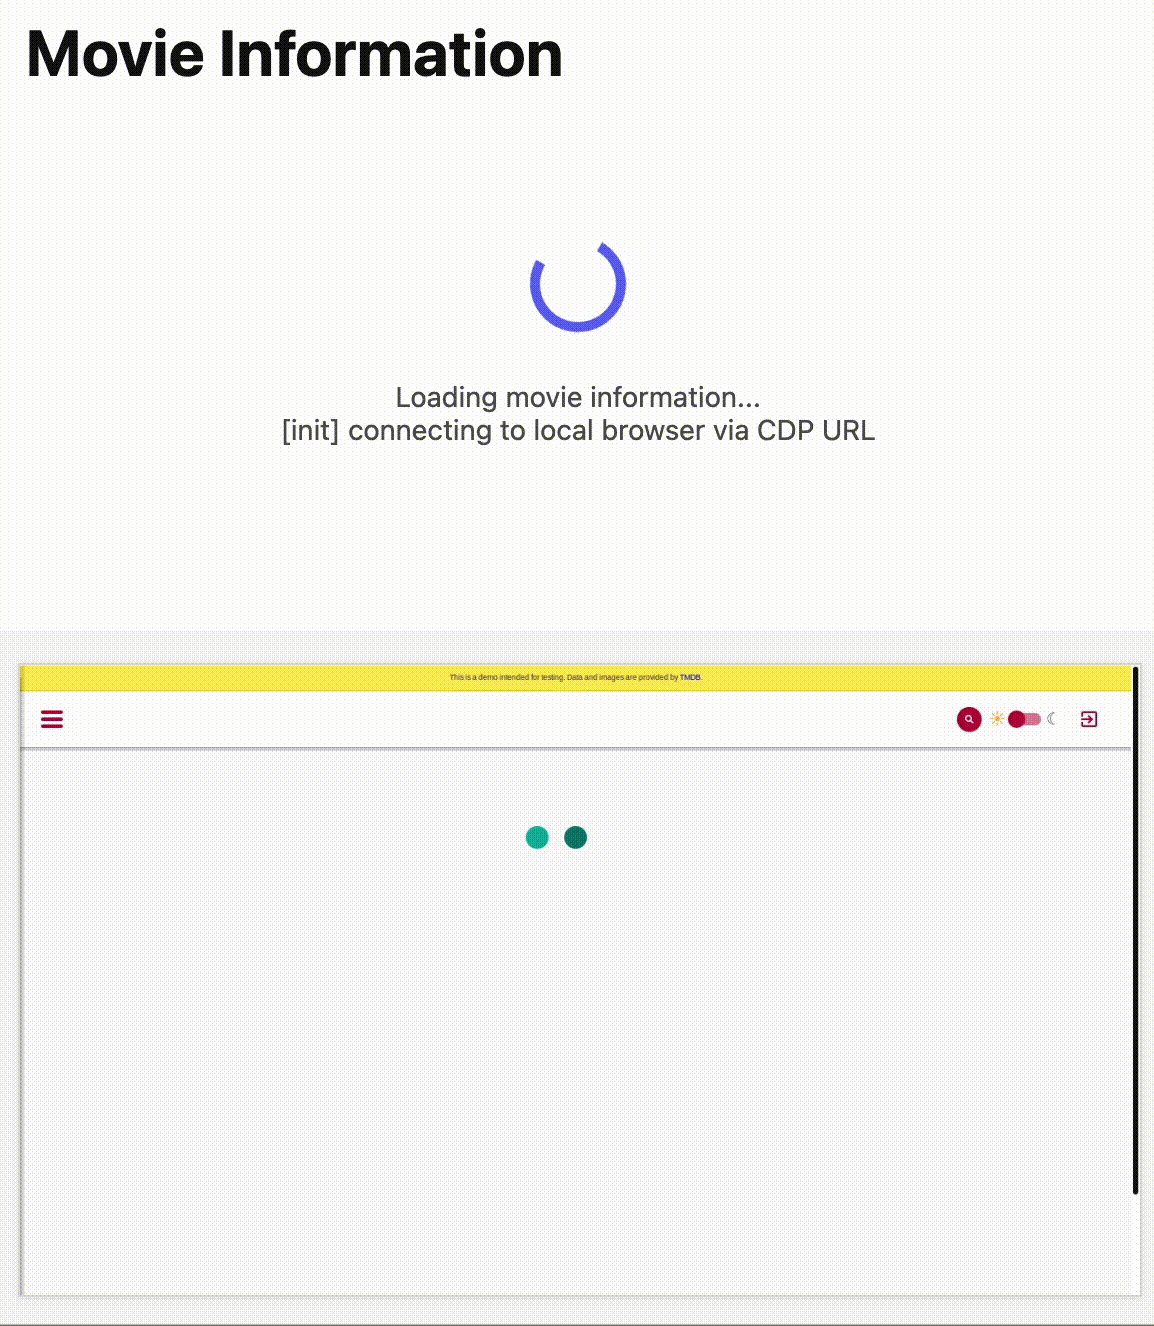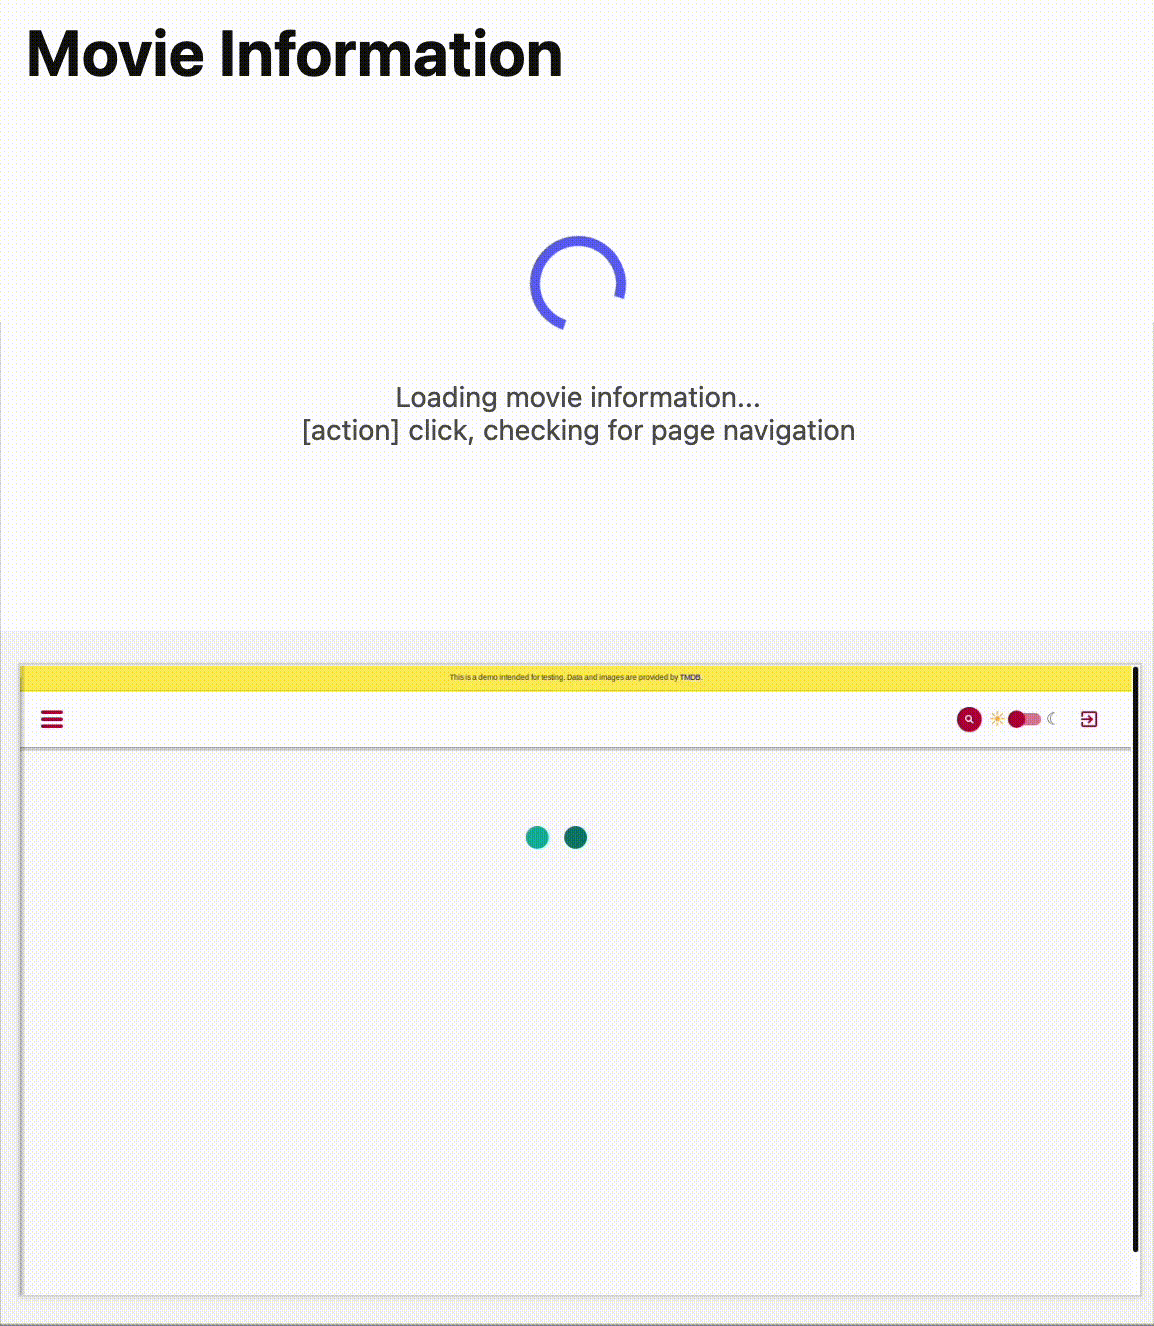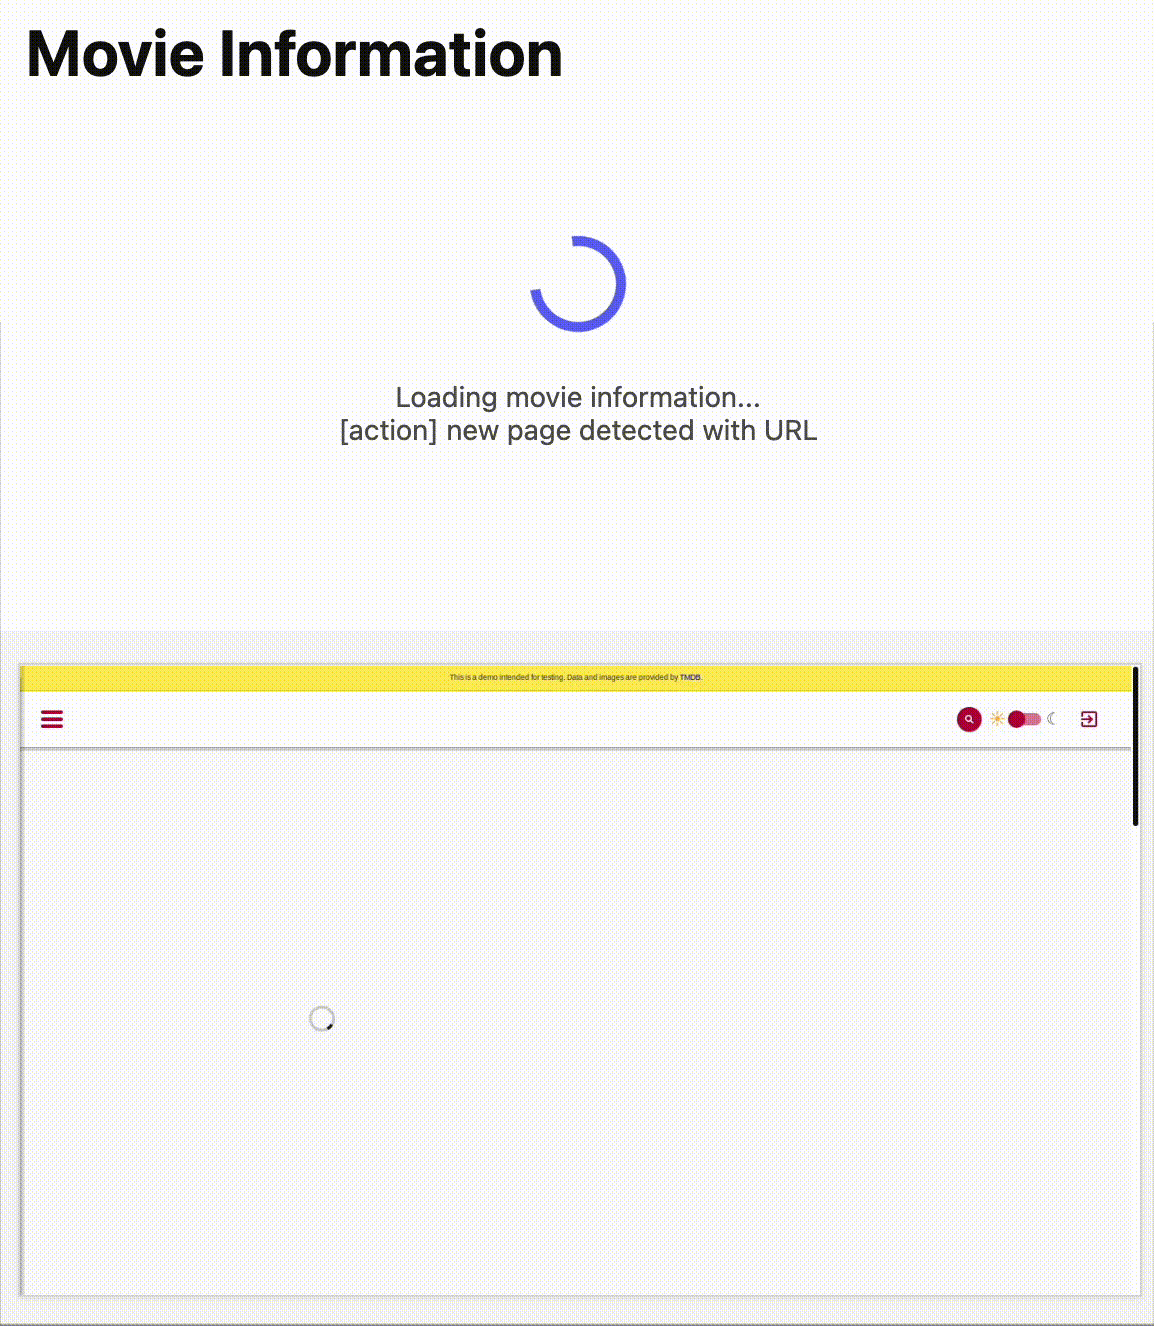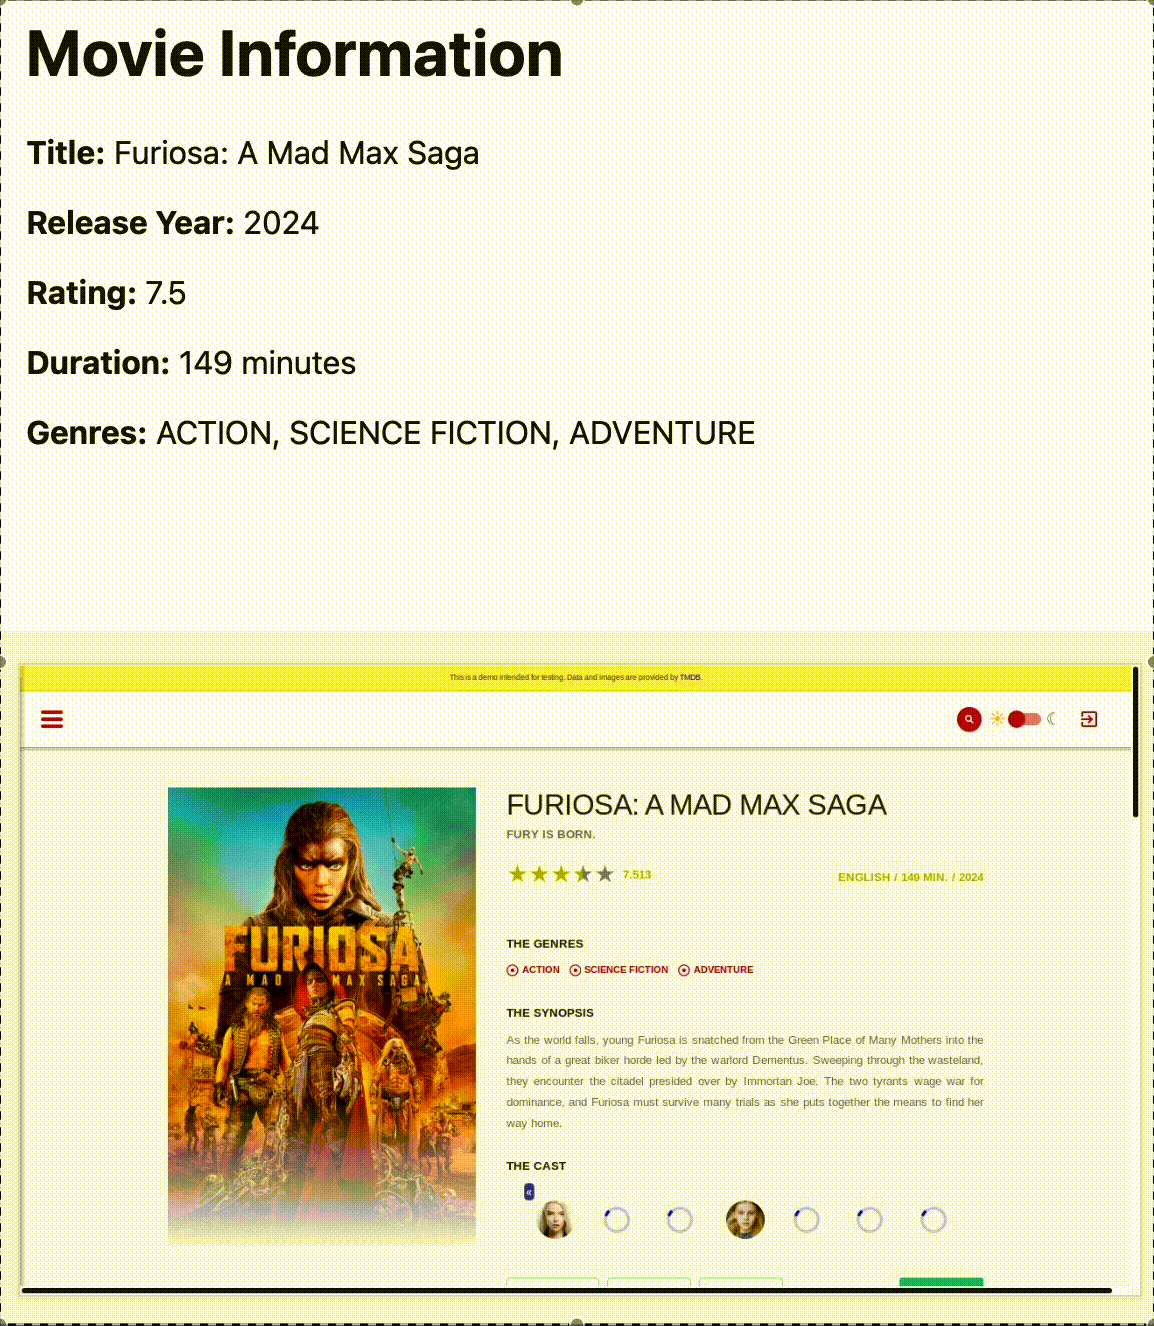
To get started with Stagehand, refer to the [Stagehand](https://developers.cloudflare.com/browser-run/stagehand/) example that uses Stagehand and [Workers AI](https://developers.cloudflare.com/workers-ai/) to search for a movie on this [example movie directory ↗︎](https://demo.playwright.dev/movies), extract its details using natural language (title, year, rating, duration, and genre), and return the information along with a screenshot of the webpage.
*Stagehand examplets*
```ts
const stagehand = new Stagehand({
env: "LOCAL",
localBrowserLaunchOptions: { cdpUrl: endpointURLString(env.BROWSER) },
llmClient: new WorkersAIClient(env.AI),
verbose: 1,
});
await stagehand.init();
const page = stagehand.page;
await page.goto("https://demo.playwright.dev/movies");
// if search is a multi-step action, stagehand will return an array of actions it needs to act on
const actions = await page.observe('Search for "Furiosa"');
for (const action of actions) await page.act(action);
await page.act("Click the search result");
// normal playwright functions work as expected
await page.waitForSelector(".info-wrapper .cast");
let movieInfo = await page.extract({
instruction: "Extract movie information",
schema: z.object({
title: z.string(),
year: z.number(),
rating: z.number(),
genres: z.array(z.string()),
duration: z.number().describe("Duration in minutes"),
}),
});
await stagehand.close();
```
Sep 25, 2025
[AI Search (formerly AutoRAG) now with More Models To Choose From
](https://developers.cloudflare.com/changelog/post/2025-09-25-ai-search-more-models/)
[AI Search](https://developers.cloudflare.com/ai-search/)
AutoRAG is now AI Search! The new name marks a new and bigger mission: to make world-class search infrastructure available to every developer and business.
With AI Search you can now use models from different providers like OpenAI and Anthropic. By attaching your provider keys to the AI Gateway linked to your AI Search instance, you can use many more models for both embedding and inference.
To use AI Search with other [model providers](https://developers.cloudflare.com/ai-search/configuration/models/):
1. **Add provider keys to AI Gateway**
1. Go to AI > AI Gateway in the dashboard.
2. Select or create an AI gateway.
3. In Provider Keys, choose your provider, click Add, and enter the key.
2. **Connect a gateway to AI Search**: When creating a new AI Search, select the AI Gateway with your provider keys. For an existing AI Search, go to Settings and switch to a gateway that has your keys under Resources.
3. **Select models**: Embedding models are only available to be changed when creating a new AI Search. Generation model can be selected when creating a new AI Search and can be changed at any time in Settings.
Once configured, your AI Search instance will be able to reference models available through your AI Gateway when making a `/ai-search` request:
```javascript
export default {
async fetch(request, env) {
// Query your AI Search instance with a natural language question to an OpenAI model
const result = await env.AI.autorag("my-ai-search").aiSearch({
query: "What's new for Cloudflare Birthday Week?",
model: "openai/gpt-5"
});
// Return only the generated answer as plain text
return new Response(result.response, {
headers: { "Content-Type": "text/plain" },
});
},
};
```
In the coming weeks we will also roll out updates to align the APIs with the new name. The existing APIs will continue to be supported for the time being. Stay tuned to the [AI Search Changelog](https://developers.cloudflare.com/changelog/product/ai-search/) and [Discord ↗︎](https://discord.cloudflare.com/) for more updates!
Sep 19, 2025
[New Metrics View in AutoRAG
](https://developers.cloudflare.com/changelog/post/2025-09-19-autorag-metrics/)
[AI Search](https://developers.cloudflare.com/ai-search/)
[AutoRAG](https://developers.cloudflare.com/ai-search/) now includes a **Metrics** tab that shows how your data is indexed and searched. Get a clear view of the health of your indexing pipeline, compare usage between `ai-search` and `search`, and see which files are retrieved most often.

You can find these metrics within each AutoRAG instance:
- Indexing: Track how files are ingested and see status changes over time.
- Search breakdown: Compare usage between `ai-search` and `search` endpoints.
- Top file retrievals: Identify which files are most frequently retrieved in a given period.
Try it today in [AutoRAG](https://developers.cloudflare.com/ai-search/get-started/).
Sep 10, 2025
[Agents SDK v0.1.0 and workers-ai-provider v2.0.0 with AI SDK v5 support
](https://developers.cloudflare.com/changelog/post/2025-09-03-agents-sdk-beta-v5/)
[Agents](https://developers.cloudflare.com/agents/) [Workers](https://developers.cloudflare.com/workers/)
We've shipped a new release for the [Agents SDK ↗︎](https://github.com/cloudflare/agents) bringing full compatibility with [AI SDK v5 ↗︎](https://ai-sdk.dev/docs/introduction) and introducing automatic message migration that handles all legacy formats transparently.
This release includes improved streaming and tool support, tool confirmation detection (for "human in the loop" systems), enhanced React hooks with automatic tool resolution, improved error handling for streaming responses, and seamless migration utilities that work behind the scenes.
This makes it ideal for building production AI chat interfaces with Cloudflare Workers AI models, agent workflows, human-in-the-loop systems, or any application requiring reliable message handling across SDK versions — all while maintaining backward compatibility.
Additionally, we've updated workers-ai-provider v2.0.0, the official provider for Cloudflare Workers AI models, to be compatible with AI SDK v5.
#### useAgentChat(options)
Creates a new chat interface with enhanced v5 capabilities.
```ts
// Basic chat setup
const { messages, sendMessage, addToolResult } = useAgentChat({
agent,
experimental_automaticToolResolution: true,
tools,
});
// With custom tool confirmation
const chat = useAgentChat({
agent,
experimental_automaticToolResolution: true,
toolsRequiringConfirmation: ["dangerousOperation"],
});
```
#### Automatic Tool Resolution
Tools are automatically categorized based on their configuration:
```ts
const tools = {
// Auto-executes (has execute function)
getLocalTime: {
description: "Get current local time",
inputSchema: z.object({}),
execute: async () => new Date().toLocaleString(),
},
// Requires confirmation (no execute function)
deleteFile: {
description: "Delete a file from the system",
inputSchema: z.object({
filename: z.string(),
}),
},
// Server-executed (no client confirmation)
analyzeData: {
description: "Analyze dataset on server",
inputSchema: z.object({ data: z.array(z.number()) }),
serverExecuted: true,
},
} satisfies Record;
```
#### Message Handling
Send messages using the new v5 format with parts array:
```ts
// Text message
sendMessage({
role: "user",
parts: [{ type: "text", text: "Hello, assistant!" }],
});
// Multi-part message with file
sendMessage({
role: "user",
parts: [
{ type: "text", text: "Analyze this image:" },
{ type: "image", image: imageData },
],
});
```
#### Tool Confirmation Detection
Simplified logic for detecting pending tool confirmations:
```ts
const pendingToolCallConfirmation = messages.some((m) =>
m.parts?.some(
(part) => isToolUIPart(part) && part.state === "input-available",
),
);
// Handle tool confirmation
if (pendingToolCallConfirmation) {
await addToolResult({
toolCallId: part.toolCallId,
tool: getToolName(part),
output: "User approved the action",
});
}
```
#### Automatic Message Migration
Seamlessly handle legacy message formats without code changes.
```ts
// All these formats are automatically converted:
// Legacy v4 string content
const legacyMessage = {
role: "user",
content: "Hello world",
};
// Legacy v4 with tool calls
const legacyWithTools = {
role: "assistant",
content: "",
toolInvocations: [
{
toolCallId: "123",
toolName: "weather",
args: { city: "SF" },
state: "result",
result: "Sunny, 72°F",
},
],
};
// Automatically becomes v5 format:
// {
// role: "assistant",
// parts: [{
// type: "tool-call",
// toolCallId: "123",
// toolName: "weather",
// args: { city: "SF" },
// state: "result",
// result: "Sunny, 72°F"
// }]
// }
```
#### Tool Definition Updates
Migrate tool definitions to use the new `inputSchema` property.
```ts
// Before (AI SDK v4)
const tools = {
weather: {
description: "Get weather information",
parameters: z.object({
city: z.string(),
}),
execute: async (args) => {
return await getWeather(args.city);
},
},
};
// After (AI SDK v5)
const tools = {
weather: {
description: "Get weather information",
inputSchema: z.object({
city: z.string(),
}),
execute: async (args) => {
return await getWeather(args.city);
},
},
};
```
#### Cloudflare Workers AI Integration
Seamless integration with Cloudflare Workers AI models through the updated workers-ai-provider v2.0.0.
#### Model Setup with Workers AI
Use Cloudflare Workers AI models directly in your agent workflows:
```ts
import { createWorkersAI } from "workers-ai-provider";
import { useAgentChat } from "agents/ai-react";
// Create Workers AI model (v2.0.0 - same API, enhanced v5 internals)
const model = createWorkersAI({
binding: env.AI,
})("@cf/meta/llama-3.2-3b-instruct");
```
#### Enhanced File and Image Support
Workers AI models now support v5 file handling with automatic conversion:
```ts
// Send images and files to Workers AI models
sendMessage({
role: "user",
parts: [
{ type: "text", text: "Analyze this image:" },
{
type: "file",
data: imageBuffer,
mediaType: "image/jpeg",
},
],
});
// Workers AI provider automatically converts to proper format
```
#### Streaming with Workers AI
Enhanced streaming support with automatic warning detection:
```ts
// Streaming with Workers AI models
const result = await streamText({
model: createWorkersAI({ binding: env.AI })("@cf/meta/llama-3.2-3b-instruct"),
messages,
onChunk: (chunk) => {
// Enhanced streaming with warning handling
console.log(chunk);
},
});
```
#### Import Updates
Update your imports to use the new v5 types:
```ts
// Before (AI SDK v4)
import type { Message } from "ai";
import { useChat } from "ai/react";
// After (AI SDK v5)
import type { UIMessage } from "ai";
// or alias for compatibility
import type { UIMessage as Message } from "ai";
import { useChat } from "@ai-sdk/react";
```
#### Resources
- [Migration Guide ↗︎](https://github.com/cloudflare/agents/blob/main/docs/migration-to-ai-sdk-v5.md) - Comprehensive migration documentation
- [AI SDK v5 Documentation ↗︎](https://ai-sdk.dev/docs/migration-guides/migration-guide-5-0) - Official AI SDK migration guide
- [An Example PR showing the migration from AI SDK v4 to v5 ↗︎](https://github.com/cloudflare/agents-starter/pull/105)
- [GitHub Issues ↗︎](https://github.com/cloudflare/agents/issues) - Report bugs or request features
#### Feedback Welcome
We'd love your feedback! We're particularly interested in feedback on:
- **Migration experience** - How smooth was the upgrade process?
- **Tool confirmation workflow** - Does the new automatic detection work as expected?
- **Message format handling** - Any edge cases with legacy message conversion?
Sep 5, 2025
[Introducing EmbeddingGemma from Google on Workers AI
](https://developers.cloudflare.com/changelog/post/2025-09-05-embeddinggemma/)
[Workers AI](https://developers.cloudflare.com/workers-ai/)
We're excited to be a launch partner alongside [Google ↗︎](https://developers.googleblog.com/en/introducing-embeddinggemma/) to bring their newest embedding model, **EmbeddingGemma**, to Workers AI that delivers best-in-class performance for its size, enabling RAG and semantic search use cases.
[`@cf/google/embeddinggemma-300m`](https://developers.cloudflare.com/workers-ai/models/embeddinggemma-300m/) is a 300M parameter embedding model from Google, built from Gemma 3 and the same research used to create Gemini models. This multilingual model supports 100+ languages, making it ideal for RAG systems, semantic search, content classification, and clustering tasks.
**Using EmbeddingGemma in AI Search:** Now you can leverage EmbeddingGemma directly through AI Search for your RAG pipelines. EmbeddingGemma's multilingual capabilities make it perfect for global applications that need to understand and retrieve content across different languages with exceptional accuracy.
To use EmbeddingGemma for your AI Search projects:
1. Go to **Create** in the [AI Search dashboard ↗︎](https://dash.cloudflare.com/?to=/:account/ai/ai-search)
2. Follow the setup flow for your new RAG instance
3. In the **Generate Index** step, open up **More embedding models** and select `@cf/google/embeddinggemma-300m` as your embedding model
4. Complete the setup to create an AI Search
Try it out and let us know what you think!
Aug 27, 2025
[Enhanced crawler insights and custom 402 responses
](https://developers.cloudflare.com/changelog/post/2025-08-27-ai-crawl-control-launch/)
[AI Crawl Control](https://developers.cloudflare.com/ai-crawl-control/)
We improved AI crawler management with detailed analytics and introduced custom HTTP 402 responses for blocked crawlers. AI Audit has been renamed to AI Crawl Control and is now generally available.
**Enhanced Crawlers tab:**
- View total allowed and blocked requests for each AI crawler
- Trend charts show crawler activity over your selected time range per crawler

**Custom block responses (paid plans):** You can now return HTTP 402 "Payment Required" responses when blocking AI crawlers, enabling direct communication with crawler operators about licensing terms.
For users on paid plans, when blocking AI crawlers you can configure:
- **Response code:** Choose between 403 Forbidden or 402 Payment Required
- **Response body:** Add a custom message with your licensing contact information

Example 402 response:
```http
HTTP 402 Payment Required
Date: Mon, 24 Aug 2025 12:56:49 GMT
Content-type: application/json
Server: cloudflare
Cf-Ray: 967e8da599d0c3fa-EWR
Cf-Team: 2902f6db750000c3fa1e2ef400000001
{
"message": "Please contact the site owner for access."
}
```
Aug 27, 2025
[Deepgram and Leonardo partner models now available on Workers AI
](https://developers.cloudflare.com/changelog/post/2025-08-27-partner-models/)
[Workers AI](https://developers.cloudflare.com/workers-ai/)
New state-of-the-art models have landed on Workers AI! This time, we're introducing new **partner models** trained by our friends at [Deepgram ↗︎](https://deepgram.com) and [Leonardo ↗︎](https://leonardo.ai), hosted on Workers AI infrastructure.
As well, we're introuding a new turn detection model that enables you to detect when someone is done speaking — useful for building voice agents!
Read the [blog ↗︎](https://blog.cloudflare.com/workers-ai-partner-models) for more details and check out some of the new models on our platform:
- [`@cf/deepgram/aura-1`](https://developers.cloudflare.com/workers-ai/models/aura-1) is a text-to-speech model that allows you to input text and have it come to life in a customizable voice
- [`@cf/deepgram/nova-3`](https://developers.cloudflare.com/workers-ai/models/nova-3) is speech-to-text model that transcribes multilingual audio at a blazingly fast speed
- [`@cf/pipecat-ai/smart-turn-v2`](https://developers.cloudflare.com/workers-ai/models/smart-turn-v2) helps you detect when someone is done speaking
- [`@cf/leonardo/lucid-origin`](https://developers.cloudflare.com/workers-ai/models/lucid-origin) is a text-to-image model that generates images with sharp graphic design, stunning full-HD renders, or highly specific creative direction
- [`@cf/leonardo/phoenix-1.0`](https://developers.cloudflare.com/workers-ai/models/phoenix-1.0) is a text-to-image model with exceptional prompt adherence and coherent text
You can filter out new partner models with the `Partner` capability on our [Models](https://developers.cloudflare.com/workers-ai/models) page.
As well, we're introducing WebSocket support for some of our audio models, which you can filter though the `Realtime` capability on our [Models](https://developers.cloudflare.com/workers-ai/models) page. WebSockets allows you to create a bi-directional connection to our inference server with low latency — perfect for those that are building voice agents.
An example python snippet on how to use WebSockets with our new Aura model:
```plaintext
import json
import os
import asyncio
import websockets
uri = f"wss://api.cloudflare.com/client/v4/accounts/{ACCOUNT_ID}/ai/run/@cf/deepgram/aura-1"
input = [
"Line one, out of three lines that will be provided to the aura model.",
"Line two, out of three lines that will be provided to the aura model.",
"Line three, out of three lines that will be provided to the aura model. This is a last line.",
]
async def text_to_speech():
async with websockets.connect(uri, additional_headers={"Authorization": os.getenv("CF_TOKEN")}) as websocket:
print("connection established")
for line in input:
print(f"sending `{line}`")
await websocket.send(json.dumps({"type": "Speak", "text": line}))
print("line was sent, flushing")
await websocket.send(json.dumps({"type": "Flush"}))
print("flushed, recving")
resp = await websocket.recv()
print(f"response received {resp}")
if __name__ == "__main__":
asyncio.run(text_to_speech())
```
Aug 26, 2025
[List all vectors in a Vectorize index with the new list-vectors operation
](https://developers.cloudflare.com/changelog/post/2025-08-26-vectorize-list-vectors/)
[Vectorize](https://developers.cloudflare.com/vectorize/)
You can now list all vector identifiers in a Vectorize index using the new `list-vectors` operation. This enables bulk operations, auditing, and data migration workflows through paginated requests that maintain snapshot consistency.
The operation is available via Wrangler CLI and REST API. Refer to the [list-vectors best practices guide](https://developers.cloudflare.com/vectorize/best-practices/list-vectors/) for detailed usage guidance.
Aug 25, 2025
[Manage and deploy your AI provider keys through Bring Your Own Key (BYOK) with AI Gateway, now powered by Cloudflare Secrets Store
](https://developers.cloudflare.com/changelog/post/2025-08-25-secrets-store-ai-gateway/)
[Secrets Store](https://developers.cloudflare.com/secrets-store/) [AI Gateway](https://developers.cloudflare.com/ai-gateway/) [SSL/TLS](https://developers.cloudflare.com/ssl/)
Cloudflare Secrets Store is now integrated with AI Gateway, allowing you to store, manage, and deploy your AI provider keys in a secure and seamless configuration through [Bring Your Own Key ↗︎](https://developers.cloudflare.com/ai-gateway/configuration/bring-your-own-keys/). Instead of passing your AI provider keys directly in every request header, you can centrally manage each key with Secrets Store and deploy in your gateway configuration using only a reference, rather than passing the value in plain text.
You can now create a secret directly from your AI Gateway [in the dashboard ↗︎](http://dash.cloudflare.com/?to=/:account/ai-gateway) by navigating into your gateway -> **Provider Keys** -> **Add**.

You can also create your secret with the newly available **ai\_gateway** scope via [wrangler ↗︎](https://developers.cloudflare.com/workers/wrangler/commands/), the [Secrets Store dashboard ↗︎](http://dash.cloudflare.com/?to=/:account/secrets-store), or the [API ↗︎](https://developers.cloudflare.com/api/resources/secrets_store/).
Then, pass the key in the request header using its Secrets Store reference:
```bash
curl -X POST https://gateway.ai.cloudflare.com/v1//my-gateway/anthropic/v1/messages \
--header 'cf-aig-authorization: ANTHROPIC_KEY_1 \
--header 'anthropic-version: 2023-06-01' \
--header 'Content-Type: application/json' \
--data '{"model": "claude-3-opus-20240229", "messages": [{"role": "user", "content": "What is Cloudflare?"}]}'
```
Or, using Javascript:
```plaintext
import Anthropic from '@anthropic-ai/sdk';
const anthropic = new Anthropic({
apiKey: "ANTHROPIC_KEY_1",
baseURL: "https://gateway.ai.cloudflare.com/v1//my-gateway/anthropic",
});
const message = await anthropic.messages.create({
model: 'claude-3-opus-20240229',
messages: [{role: "user", content: "What is Cloudflare?"}],
max_tokens: 1024
});
```
For more information, check out the [blog ↗︎](https://blog.cloudflare.com/ai-gateway-aug-2025-refresh)!
Aug 5, 2025
[Agents SDK adds MCP Elicitation support, http-streamable support, task queues, email integration and more
](https://developers.cloudflare.com/changelog/post/2025-08-05-agents-MCP-update/)
[Agents](https://developers.cloudflare.com/agents/) [Workers](https://developers.cloudflare.com/workers/)
The latest releases of [@cloudflare/agents ↗︎](https://github.com/cloudflare/agents) brings major improvements to MCP transport protocols support and agents connectivity. Key updates include:
#### MCP elicitation support
MCP servers can now request user input during tool execution, enabling interactive workflows like confirmations, forms, and multi-step processes. This feature uses durable storage to preserve elicitation state even during agent hibernation, ensuring seamless user interactions across agent lifecycle events.
```ts
// Request user confirmation via elicitation
const confirmation = await this.elicitInput({
message: `Are you sure you want to increment the counter by ${amount}?`,
requestedSchema: {
type: "object",
properties: {
confirmed: {
type: "boolean",
title: "Confirm increment",
description: "Check to confirm the increment",
},
},
required: ["confirmed"],
},
});
```
Check out our [demo ↗︎](https://github.com/whoiskatrin/agents/tree/main/examples/mcp-elicitation-demo) to see elicitation in action.
#### HTTP streamable transport for MCP
MCP now supports HTTP streamable transport which is recommended over SSE. This transport type offers:
- **Better performance**: More efficient data streaming and reduced overhead
- **Improved reliability**: Enhanced connection stability and error recover- **Automatic fallback**: If streamable transport is not available, it gracefully falls back to SSE
```ts
export default MyMCP.serve("/mcp", {
binding: "MyMCP",
});
```
The SDK automatically selects the best available transport method, gracefully falling back from streamable-http to SSE when needed.
#### Enhanced MCP connectivity
Significant improvements to MCP server connections and transport reliability:
- **Auto transport selection**: Automatically determines the best transport method, falling back from streamable-http to SSE as needed
- **Improved error handling**: Better connection state management and error reporting for MCP servers
- **Reliable prop updates**: Centralized agent property updates ensure consistency across different contexts
#### Lightweight .queue for fast task deferral
You can use `.queue()` to enqueue background work — ideal for tasks like processing user messages, sending notifications etc.
```ts
class MyAgent extends Agent {
doSomethingExpensive(payload) {
// a long running process that you want to run in the background
}
queueSomething() {
await this.queue("doSomethingExpensive", somePayload); // this will NOT block further execution, and runs in the background
await this.queue("doSomethingExpensive", someOtherPayload); // the callback will NOT run until the previous callback is complete
// ... call as many times as you want
}
}
```
Want to try it yourself? Just define a method like processMessage in your agent, and you’re ready to scale.
#### New email adapter
Want to build an AI agent that can receive and respond to emails automatically? With the new email adapter and onEmail lifecycle method, now you can.
```ts
export class EmailAgent extends Agent {
async onEmail(email: AgentEmail) {
const raw = await email.getRaw();
const parsed = await PostalMime.parse(raw);
// create a response based on the email contents
// and then send a reply
await this.replyToEmail(email, {
fromName: "Email Agent",
body: `Thanks for your email! You've sent us "${parsed.subject}". We'll process it shortly.`,
});
}
}
```
You route incoming mail like this:
```ts
export default {
async email(email, env) {
await routeAgentEmail(email, env, {
resolver: createAddressBasedEmailResolver("EmailAgent"),
});
},
};
```
You can find a full example [here ↗︎](https://github.com/cloudflare/agents/tree/main/examples/email-agent).
#### Automatic context wrapping for custom methods
Custom methods are now automatically wrapped with the agent's context, so calling `getCurrentAgent()` should work regardless of where in an agent's lifecycle it's called. Previously this would not work on RPC calls, but now just works out of the box.
```ts
export class MyAgent extends Agent {
async suggestReply(message) {
// getCurrentAgent() now correctly works, even when called inside an RPC method
const { agent } = getCurrentAgent()!;
return generateText({
prompt: `Suggest a reply to: "${message}" from "${agent.name}"`,
tools: [replyWithEmoji],
});
}
}
```
Try it out and tell us what you build!
Aug 5, 2025
[Cloudflare Sandbox SDK adds streaming, code interpreter, Git support, process control and more
](https://developers.cloudflare.com/changelog/post/2025-08-05-sandbox-sdk-major-update/)
[Agents](https://developers.cloudflare.com/agents/) [Workers](https://developers.cloudflare.com/workers/)
We’ve shipped a major release for the [@cloudflare/sandbox ↗︎](https://github.com/cloudflare/sandbox-sdk) SDK, turning it into a full-featured, container-based execution platform that runs securely on Cloudflare Workers.
This update adds live streaming of output, persistent Python and JavaScript code interpreters with rich output support (charts, tables, HTML, JSON), file system access, Git operations, full background process control, and the ability to expose running services via public URLs.
This makes it ideal for building AI agents, CI runners, cloud REPLs, data analysis pipelines, or full developer tools — all without managing infrastructure.
#### Code interpreter (Python, JS, TS)
Create persistent code contexts with support for rich visual + structured outputs.
#### createCodeContext(options)
Creates a new code execution context with persistent state.
```ts
// Create a Python context
const pythonCtx = await sandbox.createCodeContext({ language: "python" });
// Create a JavaScript context
const jsCtx = await sandbox.createCodeContext({ language: "javascript" });
```
Options:
- language: Programming language ('python' | 'javascript' | 'typescript')
- cwd: Working directory (default: /workspace)
- envVars: Environment variables for the context
#### runCode(code, options)
Executes code with optional streaming callbacks.
```ts
// Simple execution
const execution = await sandbox.runCode('print("Hello World")', {
context: pythonCtx,
});
// With streaming callbacks
await sandbox.runCode(
`
for i in range(5):
print(f"Step {i}")
time.sleep(1)
`,
{
context: pythonCtx,
onStdout: (output) => console.log("Real-time:", output.text),
onResult: (result) => console.log("Result:", result),
},
);
```
Options:
- language: Programming language ('python' | 'javascript' | 'typescript')
- cwd: Working directory (default: /workspace)
- envVars: Environment variables for the context
#### Real-time streaming output
Returns a streaming response for real-time processing.
```ts
const stream = await sandbox.runCodeStream(
"import time; [print(i) for i in range(10)]",
);
// Process the stream as needed
```
#### Rich output handling
Interpreter outputs are auto-formatted and returned in multiple formats:
- text
- html (e.g., Pandas tables)
- png, svg (e.g., Matplotlib charts)
- json (structured data)
- chart (parsed visualizations)
```ts
const result = await sandbox.runCode(
`
import seaborn as sns
import matplotlib.pyplot as plt
data = sns.load_dataset("flights")
pivot = data.pivot("month", "year", "passengers")
sns.heatmap(pivot, annot=True, fmt="d")
plt.title("Flight Passengers")
plt.show()
pivot.to_dict()
`,
{ context: pythonCtx },
);
if (result.png) {
console.log("Chart output:", result.png);
}
```
#### Preview URLs from Exposed Ports
Start background processes and expose them with live URLs.
```ts
await sandbox.startProcess("python -m http.server 8000");
const preview = await sandbox.exposePort(8000);
console.log("Live preview at:", preview.url);
```
#### Full process lifecycle control
Start, inspect, and terminate long-running background processes.
```ts
const process = await sandbox.startProcess("node server.js");
console.log(`Started process ${process.id} with PID ${process.pid}`);
// Monitor the process
const logStream = await sandbox.streamProcessLogs(process.id);
for await (const log of parseSSEStream(logStream)) {
console.log(`Server: ${log.data}`);
}
```
- listProcesses() - List all running processes
- getProcess(id) - Get detailed process status
- killProcess(id, signal) - Terminate specific processes
- killAllProcesses() - Kill all processes
- streamProcessLogs(id, options) - Stream logs from running processes
- getProcessLogs(id) - Get accumulated process output
#### Git integration
Clone Git repositories directly into the sandbox.
```ts
await sandbox.gitCheckout("https://github.com/user/repo", {
branch: "main",
targetDir: "my-project",
});
```
Sandboxes are still experimental. We're using them to explore how isolated, container-like workloads might scale on Cloudflare — and to help define the developer experience around them.
Aug 5, 2025
[OpenAI open models now available on Workers AI
](https://developers.cloudflare.com/changelog/post/2025-08-05-openai-open-models/)
[Agents](https://developers.cloudflare.com/agents/) [Workers AI](https://developers.cloudflare.com/workers-ai/)
We're thrilled to be a Day 0 partner with [OpenAI ↗︎](http://openai.com/index/introducing-gpt-oss) to bring their [latest open models ↗︎](https://openai.com/index/gpt-oss-model-card/) to Workers AI, including support for Responses API, Code Interpreter, and Web Search (coming soon).
Get started with the new models at `@cf/openai/gpt-oss-120b` and `@cf/openai/gpt-oss-20b`. Check out the [blog ↗︎](https://blog.cloudflare.com/openai-gpt-oss-on-workers-ai) for more details about the new models, and the [`gpt-oss-120b`](https://developers.cloudflare.com/workers-ai/models/gpt-oss-120b) and [`gpt-oss-20b`](https://developers.cloudflare.com/workers-ai/models/gpt-oss-20b) model pages for more information about pricing and context windows.
#### Responses API
If you call the model through:
- Workers Binding, it will accept/return Responses API – `env.AI.run(“@cf/openai/gpt-oss-120b”)`
- REST API on `/run` endpoint, it will accept/return Responses API – `https://api.cloudflare.com/client/v4/accounts//ai/run/@cf/openai/gpt-oss-120b`
- REST API on new `/responses` endpoint, it will accept/return Responses API – `https://api.cloudflare.com/client/v4/accounts//ai/v1/responses`
- REST API for OpenAI Compatible endpoint, it will return Chat Completions (coming soon) – `https://api.cloudflare.com/client/v4/accounts//ai/v1/chat/completions`
```plaintext
curl https://api.cloudflare.com/client/v4/accounts//ai/v1/responses \
-H "Content-Type: application/json" \
-H "Authorization: Bearer $CLOUDFLARE_API_KEY" \
-d '{
"model": "@cf/openai/gpt-oss-120b",
"reasoning": {"effort": "medium"},
"input": [
{
"role": "user",
"content": "What are the benefits of open-source models?"
}
]
}'
```
#### Code Interpreter
The model is natively trained to support stateful code execution, and we've implemented support for this feature using our [Sandbox SDK ↗︎](https://github.com/cloudflare/sandbox-sdk) and [Containers ↗︎](https://blog.cloudflare.com/containers-are-available-in-public-beta-for-simple-global-and-programmable/). Cloudflare's Developer Platform is uniquely positioned to support this feature, so we're very excited to bring our products together to support this new use case.
#### Web Search (coming soon)
We are working to implement Web Search for the model, where users can bring their own Exa API Key so the model can browse the Internet.
Jul 28, 2025
[Introducing pricing for the Browser Rendering API — $0.09 per browser hour
](https://developers.cloudflare.com/changelog/post/2025-07-28-br-pricing/)
[Browser Run](https://developers.cloudflare.com/browser-run/)
We’ve launched pricing for [Browser Rendering](https://developers.cloudflare.com/browser-run/), including a free tier and a pay-as-you-go model that scales with your needs. Starting **August 20, 2025**, Cloudflare will begin billing for Browser Rendering.
There are two ways to use Browser Rendering. Depending on the method you use, here’s how billing will work:
- [**REST API**](https://developers.cloudflare.com/browser-run/quick-actions/): Charged for **Duration** only ($/browser hour)
- [**Browser Sessions**](https://developers.cloudflare.com/browser-run/#integration-methods): Charged for both **Duration** and **Concurrency** ($/browser hour and # of concurrent browsers)
Included usage and pricing by plan
| Plan | Included duration | Included concurrency | Price (beyond included) |
| --- | --- | --- | --- |
| **Workers Free** | 10 minutes per day | 3 concurrent browsers | N/A |
| **Workers Paid** | 10 hours per month | 10 concurrent browsers (averaged monthly) | **1. REST API**: $0.09 per additional browser hour
**2. Workers Bindings**: $0.09 per additional browser hour
$2.00 per additional concurrent browser |
What you need to know:
- **Workers Free Plan:** 10 minutes of browser usage per day with 3 concurrent browsers at no charge.
- **Workers Paid Plan:** 10 hours of browser usage per month with 10 concurrent browsers (averaged monthly) at no charge. Additional usage is charged as shown above.
You can monitor usage via the [Cloudflare dashboard ↗︎](https://dash.cloudflare.com/?to=/:account/workers/browser-run). Go to **Compute** > **Browser Run**.

If you've been using Browser Rendering and do not wish to incur charges, ensure your usage stays within your plan's [included usage](https://developers.cloudflare.com/browser-run/pricing/). To estimate costs, take a look at these [example pricing scenarios](https://developers.cloudflare.com/browser-run/pricing/#examples-of-workers-paid-pricing).
Jul 22, 2025
[Browser Rendering now supports local development
](https://developers.cloudflare.com/changelog/post/2025-07-22-br-local-dev/)
[Browser Run](https://developers.cloudflare.com/browser-run/)
You can now run your Browser Rendering locally using `npx wrangler dev`, which spins up a browser directly on your machine before deploying to Cloudflare's global network. By running tests locally, you can quickly develop, debug, and test changes without needing to deploy or worry about usage costs.
Get started with this [example guide](https://developers.cloudflare.com/browser-run/how-to/deploy-worker/) that shows how to use Cloudflare's [fork of Puppeteer](https://developers.cloudflare.com/browser-run/puppeteer/) (you can also use [Playwright](https://developers.cloudflare.com/browser-run/playwright/)) to take screenshots of webpages and store the results in [Workers KV](https://developers.cloudflare.com/kv/).
Jul 8, 2025
[Faster indexing and new Jobs view in AutoRAG
](https://developers.cloudflare.com/changelog/post/2025-07-08-autorag-jobs-view/)
[AI Search](https://developers.cloudflare.com/ai-search/)
You can now expect **3-5× faster indexing** in AutoRAG, and with it, a brand new **Jobs view** to help you monitor indexing progress.
With each AutoRAG, indexing jobs are automatically triggered to sync your data source (i.e. R2 bucket) with your Vectorize index, ensuring new or updated files are reflected in your query results. You can also trigger jobs manually via the [Sync API](https://developers.cloudflare.com/api/resources/ai-search/subresources/rags/) or by clicking “Sync index” in the dashboard.
With the new jobs observability, you can now:
- View the status, job ID, source, start time, duration and last sync time for each indexing job
- Inspect real-time logs of job events (e.g. `Starting indexing data source...`)
- See a history of past indexing jobs under the Jobs tab of your AutoRAG
This makes it easier to understand what’s happening behind the scenes.
**Coming soon:** We’re adding APIs to programmatically check indexing status, making it even easier to integrate AutoRAG into your workflows.
Try it out today on the [Cloudflare dashboard ↗︎](https://dash.cloudflare.com/?to=/:account/ai/autorag).
Jul 1, 2025
[Introducing Pay Per Crawl (private beta)
](https://developers.cloudflare.com/changelog/post/2025-07-01-pay-per-crawl/)
[AI Crawl Control](https://developers.cloudflare.com/ai-crawl-control/)
We are introducing a new feature of [AI Crawl Control](https://developers.cloudflare.com/ai-crawl-control/) — Pay Per Crawl. [Pay Per Crawl](https://developers.cloudflare.com/ai-crawl-control/features/pay-per-crawl/what-is-pay-per-crawl/) enables site owners to require payment from AI crawlers every time the crawlers access their content, thereby fostering a fairer Internet by enabling site owners to control and monetize how their content gets used by AI.

**For Site Owners:**
- Set pricing and select which crawlers to charge for content access
- Manage payments via Stripe
- Monitor analytics on successful content deliveries
**For AI Crawler Owners:**
- Use HTTP headers to request and accept pricing
- Receive clear confirmations on charges for accessed content
Learn more in the [Pay Per Crawl documentation](https://developers.cloudflare.com/ai-crawl-control/features/pay-per-crawl/what-is-pay-per-crawl/).
Jul 1, 2025
[AI Crawl Control refresh
](https://developers.cloudflare.com/changelog/post/2025-07-01-refresh/)
[AI Crawl Control](https://developers.cloudflare.com/ai-crawl-control/)
We redesigned the AI Crawl Control dashboard to provide more intuitive and granular control over AI crawlers.
- From the new **AI Crawlers** tab: block specific AI crawlers.
- From the new **Metrics** tab: view AI Crawl Control metrics.
 
To get started, explore:
- [Manage AI crawlers](https://developers.cloudflare.com/ai-crawl-control/features/manage-ai-crawlers/).
- [Analyze AI traffic](https://developers.cloudflare.com/ai-crawl-control/features/analyze-ai-traffic/).
Jun 25, 2025
[Run AI-generated code on-demand with Code Sandboxes (new)
](https://developers.cloudflare.com/changelog/post/2025-06-24-announcing-sandboxes/)
[Agents](https://developers.cloudflare.com/agents/) [Workers](https://developers.cloudflare.com/workers/) [Workflows](https://developers.cloudflare.com/workflows/)
AI is supercharging app development for everyone, but we need a safe way to run untrusted, LLM-written code. We’re introducing [Sandboxes ↗︎](https://www.npmjs.com/package/@cloudflare/sandbox), which let your Worker run actual processes in a secure, container-based environment.
```ts
import { getSandbox } from "@cloudflare/sandbox";
export { Sandbox } from "@cloudflare/sandbox";
export default {
async fetch(request: Request, env: Env) {
const sandbox = getSandbox(env.Sandbox, "my-sandbox");
return sandbox.exec("ls", ["-la"]);
},
};
```
#### Methods
- `exec(command: string, args: string[], options?: { stream?: boolean })`:Execute a command in the sandbox.
- `gitCheckout(repoUrl: string, options: { branch?: string; targetDir?: string; stream?: boolean })`: Checkout a git repository in the sandbox.
- `mkdir(path: string, options: { recursive?: boolean; stream?: boolean })`: Create a directory in the sandbox.
- `writeFile(path: string, content: string, options: { encoding?: string; stream?: boolean })`: Write content to a file in the sandbox.
- `readFile(path: string, options: { encoding?: string; stream?: boolean })`: Read content from a file in the sandbox.
- `deleteFile(path: string, options?: { stream?: boolean })`: Delete a file from the sandbox.
- `renameFile(oldPath: string, newPath: string, options?: { stream?: boolean })`: Rename a file in the sandbox.
- `moveFile(sourcePath: string, destinationPath: string, options?: { stream?: boolean })`: Move a file from one location to another in the sandbox.
- `ping()`: Ping the sandbox.
Sandboxes are still experimental. We're using them to explore how isolated, container-like workloads might scale on Cloudflare — and to help define the developer experience around them.
You can try it today from your Worker, with just a few lines of code. Let us know what you build.
Jun 19, 2025
[View custom metadata in responses and guide AI-search with context in AutoRAG
](https://developers.cloudflare.com/changelog/post/2025-06-19-autorag-custom-metadata-and-context/)
[AI Search](https://developers.cloudflare.com/ai-search/)
In [AutoRAG](https://developers.cloudflare.com/ai-search/), you can now view your object's custom metadata in the response from [`/search`](https://developers.cloudflare.com/ai-search/api/search/workers-binding/) and [`/ai-search`](https://developers.cloudflare.com/ai-search/api/search/workers-binding/), and optionally add a `context` field in the custom metadata of an object to provide additional guidance for AI-generated answers.
You can add [custom metadata](https://developers.cloudflare.com/r2/api/workers/workers-api-reference/#r2putoptions) to an object when uploading it to your R2 bucket.
#### Object's custom metadata in search responses
When you run a search, AutoRAG now returns any custom metadata associated with the object. This metadata appears in the response inside `attributes` then `file` , and can be used for downstream processing.
For example, the `attributes` section of your search response may look like:
```json
{
"attributes": {
"timestamp": 1750001460000,
"folder": "docs/",
"filename": "launch-checklist.md",
"file": {
"url": "https://wiki.company.com/docs/launch-checklist",
"context": "A checklist for internal launch readiness, including legal, engineering, and marketing steps."
}
}
}
```
#### Add a `context` field to guide LLM answers
When you include a custom metadata field named `context`, AutoRAG attaches that value to each chunk of the file. When you run an `/ai-search` query, this `context` is passed to the LLM and can be used as additional input when generating an answer.
We recommend using the `context` field to describe supplemental information you want the LLM to consider, such as a summary of the document or a source URL. If you have several different metadata attributes, you can join them together however you choose within the `context` string.
For example:
```json
{
"context": "summary: 'Checklist for internal product launch readiness, including legal, engineering, and marketing steps.'; url: 'https://wiki.company.com/docs/launch-checklist'"
}
```
This gives you more control over how your content is interpreted, without requiring you to modify the original contents of the file.
Learn more in AutoRAG's [metadata filtering documentation](https://developers.cloudflare.com/ai-search/configuration/indexing/metadata/).
```json
{"@context":"https://schema.org","@type":"BlogPosting","@id":"https://developers.cloudflare.com/changelog/product-group/ai/8/#page","headline":"AI Changelog","url":"https://developers.cloudflare.com/changelog/product-group/ai/8/","inLanguage":"en","image":"https://developers.cloudflare.com/og-changelog.png","publisher":{"@type":"Organization","name":"Cloudflare","description":"One platform for your apps, agents, and workforce. Build, secure, and scale without managing infrastructure","url":"https://www.cloudflare.com/","sameAs":["https://github.com/cloudflare","https://www.linkedin.com/company/cloudflare","https://x.com/cloudflare"],"logo":{"@type":"ImageObject","url":"https://developers.cloudflare.com/logo.svg"},"address":{"@type":"PostalAddress","streetAddress":"101 Townsend St","addressLocality":"San Francisco","addressRegion":"CA","postalCode":"94107","addressCountry":"US"},"contactPoint":[{"@type":"ContactPoint","contactType":"Customer Support","url":"https://support.cloudflare.com/","availableLanguage":["English"]},{"@type":"ContactPoint","contactType":"Sales","url":"https://www.cloudflare.com/contact/","availableLanguage":["English"]}]},"isPartOf":{"@type":"WebSite","@id":"https://developers.cloudflare.com/#website","name":"Cloudflare Docs","url":"https://developers.cloudflare.com/"}}
```